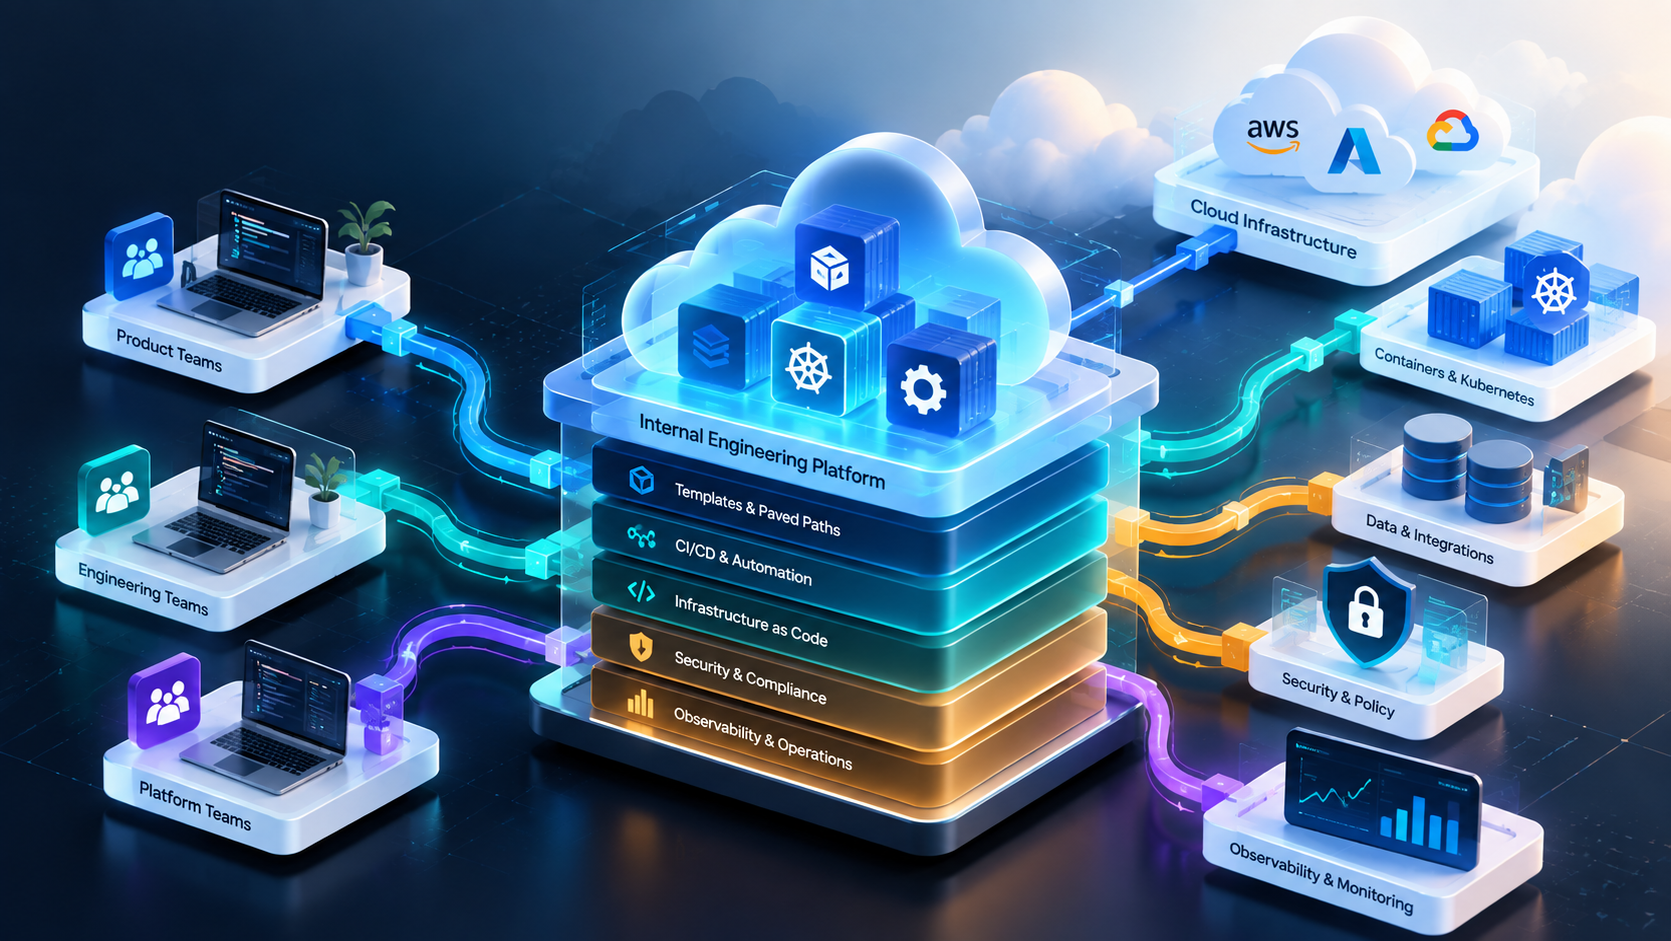
Internal developer portals have become one of the most visible expressions of platform engineering.
That visibility can also create a misconception.
A portal can make services easier to discover. It can expose documentation, environments, templates and operational information through a cleaner interface. It can remove friction from common developer tasks.
Those are valuable outcomes.
But a portal is not the platform.
Platform engineering becomes strategically useful when it changes the underlying experience of building, deploying and operating software — not merely the interface through which developers request infrastructure.
The distinction matters because organizations can build an elegant developer portal while leaving most of the original delivery complexity untouched underneath it.
The portal is the interface. The platform is the capability.
Consider what happens when a developer selects “Create Service” inside an internal portal.
The button itself is not particularly valuable.
The value comes from what happens behind it.
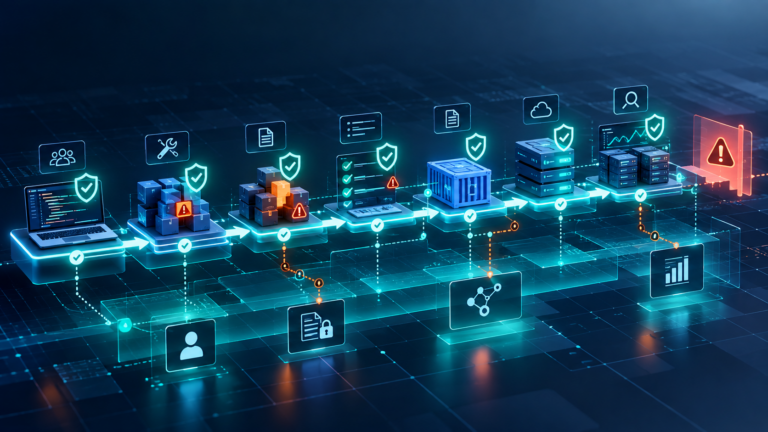
- A repository may be created with approved structure and conventions.
- A CI/CD pipeline may be provisioned automatically.
- Infrastructure may be created using governed templates.
- Identity and access controls may be applied.
- Logging, metrics and tracing may be enabled.
- Security scanning may become part of the delivery path.
- Deployment policies may be inherited.
- Ownership and operational metadata may be registered.
That collection of reusable capabilities is the platform.
The portal simply makes those capabilities easier to consume.
This is why mature platform engineering is closely connected to Cloud & DevOps, infrastructure automation, software architecture, security and operational engineering rather than being primarily a user-interface project.
Good platforms reduce cognitive load, not engineering judgment.
Software teams make an enormous number of decisions.
How should a service be structured? How is infrastructure provisioned? Where are secrets stored? How are releases promoted? Which monitoring conventions apply? How should workloads authenticate? Which deployment pattern is approved?
Some decisions are genuinely specific to the product being built.
Others are repeatedly solved across dozens or hundreds of teams.
Platform engineering creates leverage by separating the two.
Teams should retain engineering judgment where the product requires it.
They should not have to rediscover the organization’s preferred answer to every infrastructure, delivery, security and observability question.
This is the purpose of a paved path or golden path: a supported route through a common engineering problem that already incorporates sensible defaults, reusable automation and organizational controls.
A good paved path does not prohibit every alternative.
It simply makes the normal path dramatically easier than rebuilding the same capability independently.
Self-service matters only when something meaningful has been automated.
Self-service is another phrase frequently associated with platform engineering.
But self-service should mean more than replacing a service desk ticket with a web form.
If a developer clicks a button and the request still enters a manual queue, little has changed structurally.
Effective self-service connects the developer experience to automated platform capabilities.
Depending on the environment, that may include:
- application and repository scaffolding;
- environment provisioning;
- CI/CD pipeline creation;
- infrastructure-as-code modules;
- container and Kubernetes deployment patterns;
- managed databases or messaging services;
- secrets and identity configuration;
- DNS and networking requests;
- observability setup;
- security and policy controls; and
- service registration and documentation.
The objective is not automation for its own sake.
It is to shorten the distance between an engineering intent and a correctly configured operational capability.
The platform should encode operational knowledge.
Organizations accumulate engineering knowledge over time.
They learn which deployment patterns create unnecessary risk. Which observability conventions make incidents easier to diagnose. Which security controls are repeatedly missed. Which cloud configurations lead to cost problems. Which release processes produce unnecessary delays.
Without a platform, much of that knowledge remains fragmented across documents, individual teams and informal experience.
A mature internal platform converts part of that knowledge into reusable system behaviour.
For example:
- approved infrastructure modules can encode infrastructure standards;
- service templates can encode architectural conventions;
- pipeline components can embed testing and release controls;
- default telemetry can make services observable from their first deployment;
- policy-as-code can enforce important controls consistently; and
- standard operational metadata can improve ownership and incident response.
That is substantially more powerful than publishing another engineering standards document.
The preferred behaviour becomes easier to adopt because it is built into the delivery system.
Security works better when the platform carries part of the burden.
Security requirements often become expensive when every application team has to interpret and implement them independently.
Platform engineering creates an opportunity to move appropriate controls into shared capabilities.
That might include:
- approved base images;
- dependency and container scanning;
- secret-management integration;
- identity defaults;
- infrastructure policies;
- code-analysis stages;
- deployment controls; and
- standard logging or audit mechanisms.
The goal is not to transfer all responsibility from development teams to the platform team.
It is to make secure behaviour easier to achieve consistently.
This is the same principle behind mature Cybersecurity and DevSecOps practices: controls are more effective when they participate in the engineering system rather than arriving only at the end of delivery.
A platform team should behave like a product team.
One of the most important platform-engineering ideas is also one of the easiest to overlook.
The platform has users.
Those users are developers, architects, SREs, testers, security engineers and other technology teams.
If those users find the platform difficult, restrictive or unreliable, they will work around it.
That means platform teams need product-management disciplines.
They need to understand:
- where developers lose time;
- which repeated tasks generate the most friction;
- which capabilities teams actually need;
- where existing paved paths are too restrictive;
- which documentation is difficult to understand;
- where platform reliability is affecting delivery; and
- which features create measurable improvement.
The platform roadmap should therefore not be determined only by infrastructure preferences.
It should be shaped by the engineering problems its users are trying to solve.
The wrong metrics can make a platform look successful.
A portal can attract thousands of page views.
A platform can provide dozens of templates.
Neither tells us whether software delivery actually improved.
Useful platform metrics should connect adoption to engineering outcomes.
Depending on the organization, that may mean examining:
- time required to create a production-ready service;
- developer onboarding time;
- lead time for common infrastructure requests;
- deployment frequency;
- change failure rate;
- mean time to restore service;
- percentage of services using supported platform patterns;
- frequency of manual platform interventions;
- developer satisfaction;
- platform reliability; and
- duplicated engineering effort avoided through reusable capabilities.
No single metric describes developer productivity perfectly.
But the measurement principle is straightforward:
The platform should be judged by whether it improves the engineering system, not by how many features the platform team ships.
Common ways platform engineering loses its purpose.
Platform initiatives can become sophisticated technically while still failing to reduce delivery friction.
Building the portal before understanding the platform.
The organization creates an attractive service catalogue before building the reusable capabilities that should sit behind it.
The result is a better interface over largely unchanged processes.
Turning the platform team into another ticket queue.
If every developer request still requires platform-team intervention, the organization has centralized infrastructure work rather than created a self-service platform.
Confusing standardization with inflexibility.
A paved path should solve the common case well.
It should not force every workload into the same architecture regardless of legitimate product requirements.
Building technology nobody chooses to use.
Mandated adoption can hide poor developer experience.
A strong platform should earn adoption by making the supported path materially easier.
Expanding the platform faster than it can be operated.
Every abstraction, service and template becomes something that eventually needs maintenance, documentation and support.
A smaller reliable platform is often more valuable than a large catalogue of poorly maintained capabilities.
A practical progression for platform engineering.
Organizations do not need to build a comprehensive internal developer platform on day one.
A more useful progression starts with recurring engineering friction.
01 — Identify repeated delivery problems.
Find the tasks teams solve repeatedly: service creation, environments, deployments, observability, identity, infrastructure or security configuration.
02 — Standardize only where repetition exists.
Do not abstract a problem before the organization understands it.
Stable patterns make better platform capabilities.
03 — Automate the underlying capability.
Build reusable APIs, templates, modules and workflows before concentrating on the front-end experience.
04 — Create paved paths around high-value workflows.
Make common engineering journeys easy, repeatable and supportable.
05 — Add the portal where discoverability becomes the problem.
Once capabilities exist, a portal can provide a coherent product experience around them.
06 — Measure whether developer outcomes improve.
Track engineering friction, reliability, lead time, adoption and user experience.
Then evolve the platform based on evidence.
The platform is ultimately an engineering leverage system.
The strongest case for platform engineering is not that every organization needs an internal developer portal.
It is that engineering organizations repeatedly spend valuable time solving the same enabling problems.
Provisioning environments. Configuring deployment pipelines. Integrating observability. Implementing security controls. Discovering services. Managing infrastructure. Establishing operational conventions.
When those problems are solved once as reusable capabilities, individual product teams can spend more of their attention on the systems that differentiate the business.
That is the real promise of platform engineering.
Not another layer of tooling.
Not a prettier infrastructure request form.
And not a portal for its own sake.
A well-designed internal platform turns repeated engineering knowledge into reusable capability — making the right path easier to discover, easier to use and easier to operate at scale.
That is where platform engineering intersects most directly with Product & Platform Engineering: both are ultimately about building systems that allow technology organizations to change and deliver more effectively.